#Large Language Models
 AI
VRAM for Local LLMs: How Much Each Model Size Needs at Every Quantization Level
A reference chart of memory needs for 8B to 70B models at Q4, Q8, and FP16, plus context overhead, Apple Silicon limits, GPU fit, and a formula.
 AI
How to Run an LLM Locally With Ollama: Setup for Windows, Mac, and Linux
Ollama runs open models on Windows, macOS, and Linux. Hardware needs by model size, install steps, a first chat, and the local API on port 11434.
 AI
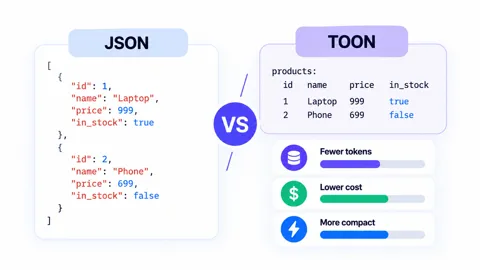
JSON vs TOON: Token Usage, Cost, and Key Differences
JSON vs TOON explained: compare token usage, API cost, accuracy, and compatibility, then learn when TOON is worth testing for LLM prompts.
 AI
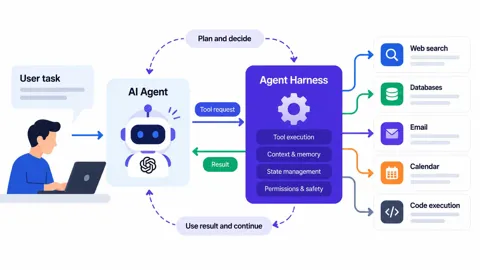
What Is an AI Agent Harness? How It Works and Why It Matters
An AI agent harness connects a model to tools, context, execution, and safety controls. Here is how it works and why reliable agents need it.
 AI
Mistral Large 4 Makes France a Serious AI Contender Again - But There's a Catch
Mistral Large 4 reaches 38 on Artificial Analysis, putting France's model at the top outside the U.S. and China while its task cost remains high.
 AI
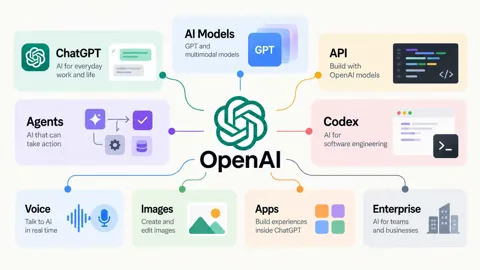
What Does OpenAI Do? A Complete Guide to ChatGPT, Models, APIs, Agents, and Codex
What Does OpenAI Do? This guide explains how OpenAI's models, ChatGPT, APIs, agents, Codex, tools, voice, images, and apps fit together for readers.
 AI
Google Launches Gemini 4 Argon With a 1 Million-Token Output Limit
Gemini 4 Argon raises Google’s output limit from 64K to 1 million tokens for long coding, enterprise, and cybersecurity workflows in its first rollout.
 AI
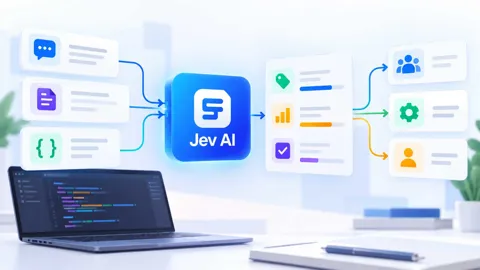
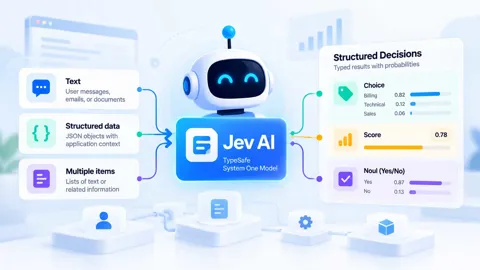
How to Use Jev AI: A Practical Guide for Developers and AI Agents
Learn how to use Jev AI in a real application, from defining a decision and preparing state to calling the API and handling structured results safely.
 AI
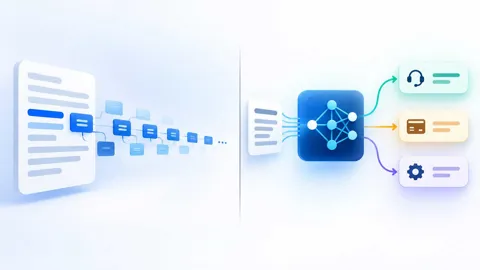
What Is Jev AI? How TypeSafe’s System One Decision Model Works
Learn what Jev AI is, how TypeSafe’s System One model works, and how typed decisions differ from generative LLM outputs in AI applications today.
 AI
Why Decision Models Like Jev Can Be Much Faster Than LLMs
Decision models answer bounded software questions without generating text. Jev shows how that can reduce latency and simplify routing, scoring, and triage.
 AI
OpenAI's Data Agent Turns Questions Into Power BI and Tableau Dashboards
OpenAI's new Data agent in ChatGPT Work can analyze connected company data and build dashboards in Power BI, Tableau, and other BI tools.
 AI
DeepSeek V4.1 Flash Launches With Native Vision and Lower AI Inference Costs
DeepSeek V4.1 Flash brings native visual understanding, a 552B MoE architecture, lower cache overhead, and new API pricing.